NVIDIA Unveils RTX Spark Laptops with 74B Nemotron-3.5 Bolt
🚀 Local AI Revolution: 74B Model Squeezed into Laptops
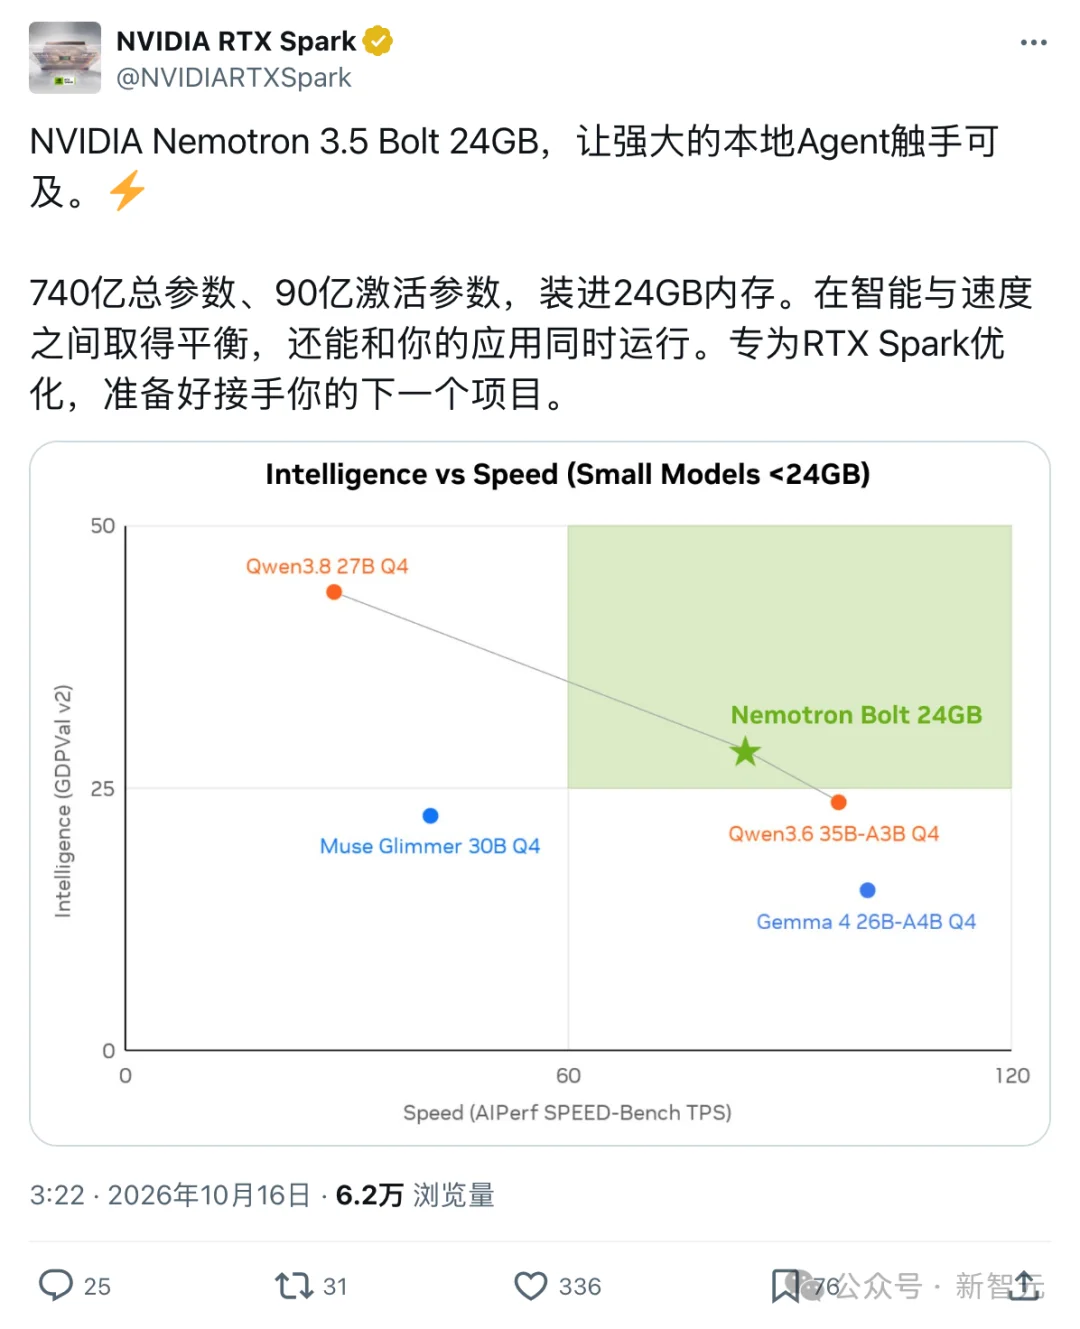
Just announced, NVIDIA has open-sourced the Nemotron-3.5 Bolt model weights — a groundbreaking 74-billion-parameter multimodal AI designed for on-device agent workloads. Through aggressive quantization and architecture optimization, NVIDIA compressed the model from ~148 GB (BF16) down to just 22.1 GB, enabling full local inference on high-end laptops equipped with RTX Spark.
This marks a paradigm shift: no more round-trips to the cloud. Agents can now read files, edit code, call tools, and process images — all natively on your machine.
🔍 How Bolt Works: Smarter, Leaner, Faster
- Dynamic Parameter Activation: While housing 74B parameters, Bolt activates only ~9B tokens per generation — balancing capability and efficiency.
- Multimodal Ready: Supports text, image, and video inputs; excels at terminal operations and web browsing tasks.
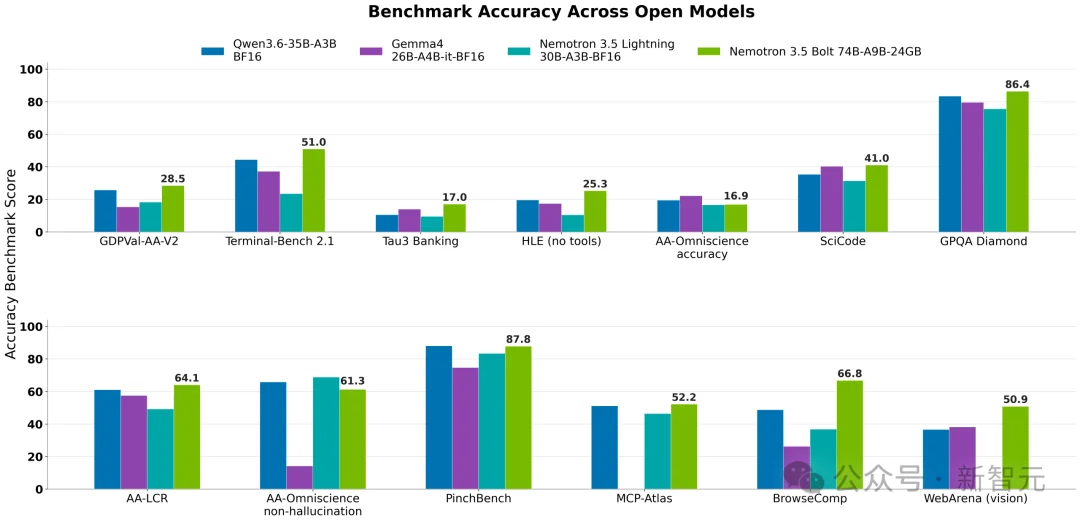
- Benchmark Performance:
- Terminal-Bench 2.1: 50.98% — proving robust CLI interaction
- BrowseComp: 66.75% — demonstrating strong real-world web navigation
Ollama already provides ready-to-run integrations with OpenClaw, Hermes, and other agent frameworks — letting developers swap cloud models for local inference in minutes.
🧠 From Super VL to Bolt: The Compression Journey
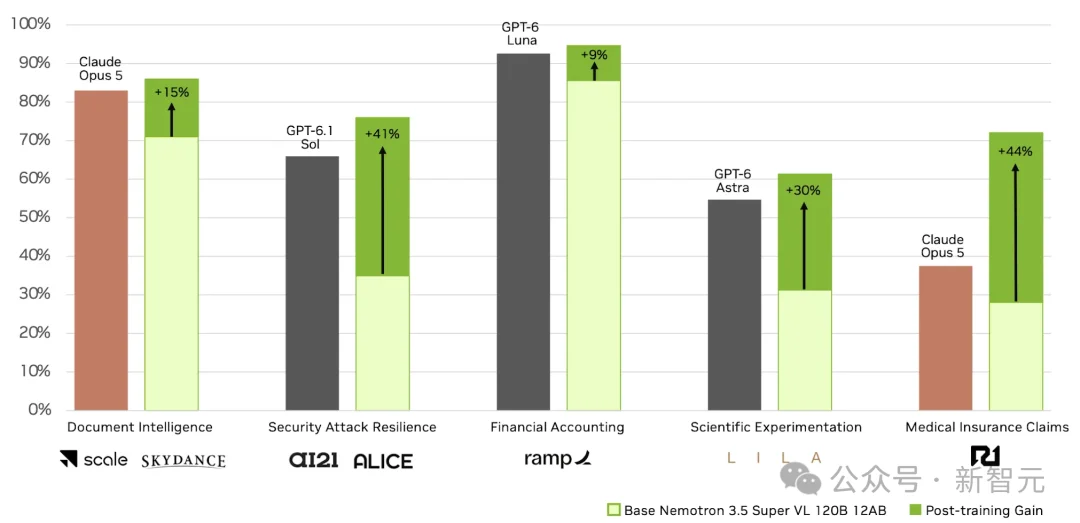
Bolt is derived from the enterprise-grade 1200B Nemotron-3.5 Super VL, which activates 12B parameters and handles complex documents, charts, and videos. To adapt it for laptops:
- Structural Pruning: Reduced from 1200B → 740B parameters while preserving core reasoning.
- Vision Module Retraining: Initial compression dropped ScreenSpot Pro accuracy from 41.6% → 0%. Restored to 39.79% via targeted visual adapter training on ~6.6M synthetic screen images.
- Quantization & Distillation: Expert weights compressed to ~2-bit, complemented by quantization-aware distillation — recovering precision lost during shrinking.
The result? A lean, intelligent, and responsive local model that doesn’t sacrifice capability for portability.
💻 RTX Spark Hardware: Built for Local AI
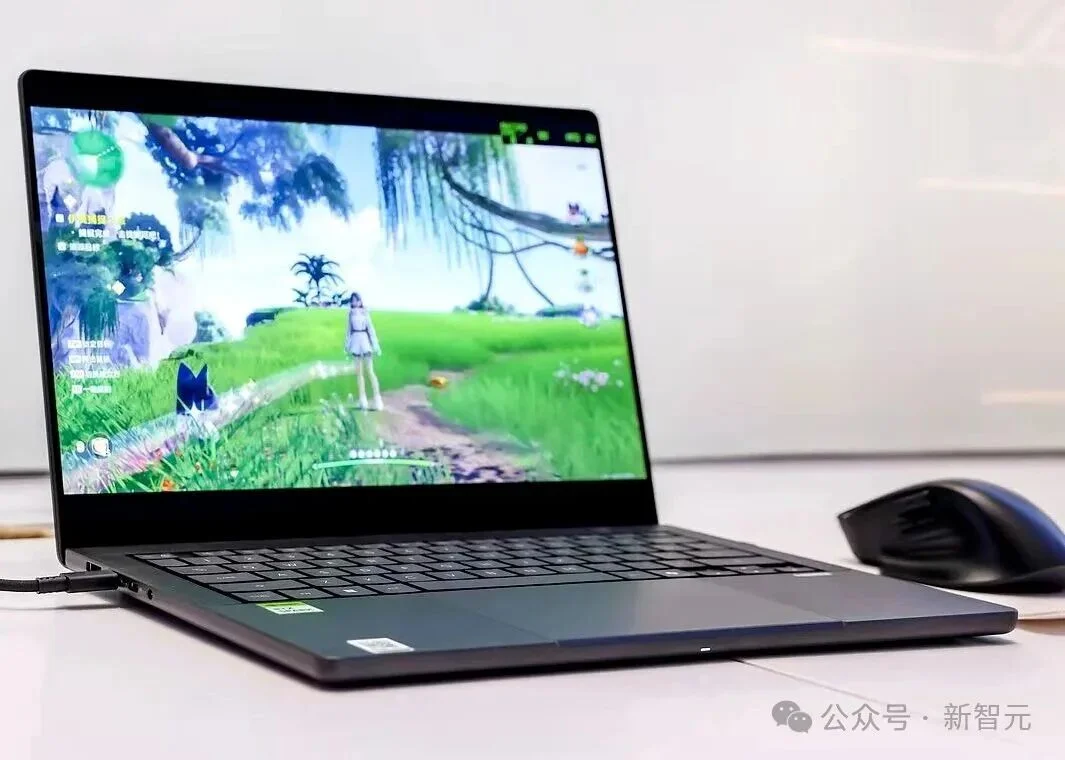
Launched globally on October 16, 2026, RTX Spark laptops — from Lenovo, Microsoft, and others — feature:
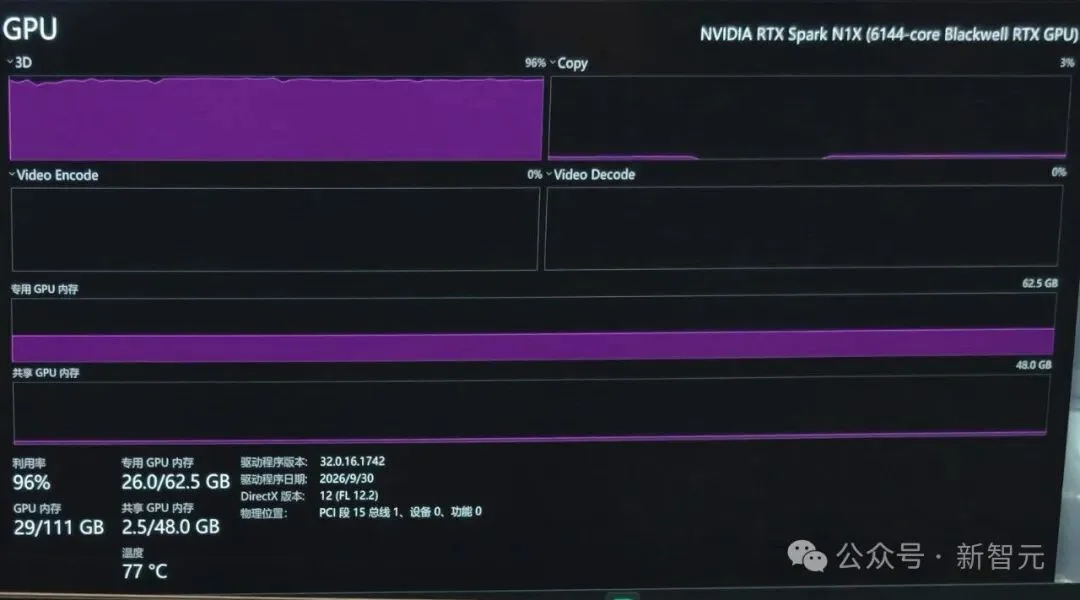
- Unified Memory Architecture: Up to 128 GB shared CPU/GPU memory, eliminating bottlenecks for large-model loading.
- Real-World Speed: On a Surface Laptop Ultra (128GB RTX Spark), Bolt achieves ~84 tokens/sec in NVIDIA’s code-generation benchmarks.
- Practical Memory Guidance:
- ✅ Minimum recommended: 32 GB unified memory (for short-context use)
- 🟡 Comfortable range: 48–64 GB (for multitasking + vision modules + LiLiCorr draft model)
- ⚠️ Note: 22.1 GB = model weights only — cache, accelerators, and vision layers require headroom.
🌐 Ecosystem & Use Cases: Beyond the Lab
- Enterprise Adoption: Ramp uses Nemotron-3.5 Super VL to parse receipts — extracting merchant, date, and amounts into structured, API-ready data.
- Developer Tooling: Pre-integrated with OpenClaw and Hermes; one-click setup reduces deployment friction.
- Consumer-Ready Multitasking: RTX Spark laptops also natively support Photoshop, Premiere Pro (beta), and 100+ AAA games — proving AI doesn’t replace productivity, it enhances it.
📦 Coming Soon: Bolt E4B (4GB) for Edge Devices
Slated for release on October 23, 2026, the Nemotron-3.5 Bolt E4B brings lightweight local intelligence to:
– Voice assistants
– Embedded interactive characters
– Low-power edge devices
Three tiers, one strategy: Super VL → Bolt → E4B, each optimized for its environment — from data centers to desktops to earbuds.

📚 References
“Your laptop isn’t just a tool anymore — it’s an AI co-pilot. And now, it’s got its own brain.”