Google Launches Gemini 3.5 Transcribe: The Foundation for Voice Agents
A Next-Generation Speech-to-Text Model Designed for Real-World Complexity
On August 26, Google unveiled Gemini 3.5 Transcribe, its latest speech-to-text model—marketed as the most accurate yet. Unlike traditional ASR systems focused solely on verbatim transcription, Gemini 3.5 Transcribe performs intelligent post-processing: automatically removing filler words (e.g., “um”, “ah”), resolving self-corrections (e.g., “Tuesday — no, Wednesday”), inserting punctuation and capitalization, and normalizing spoken numbers (e.g., “twenty six million dollars” → “$26M”).
✅ Key differentiator: It outputs production-ready text, not raw transcripts — reducing manual editing for meeting notes, interviews, and call logs.
Multilingual, Adaptive & Context-Aware
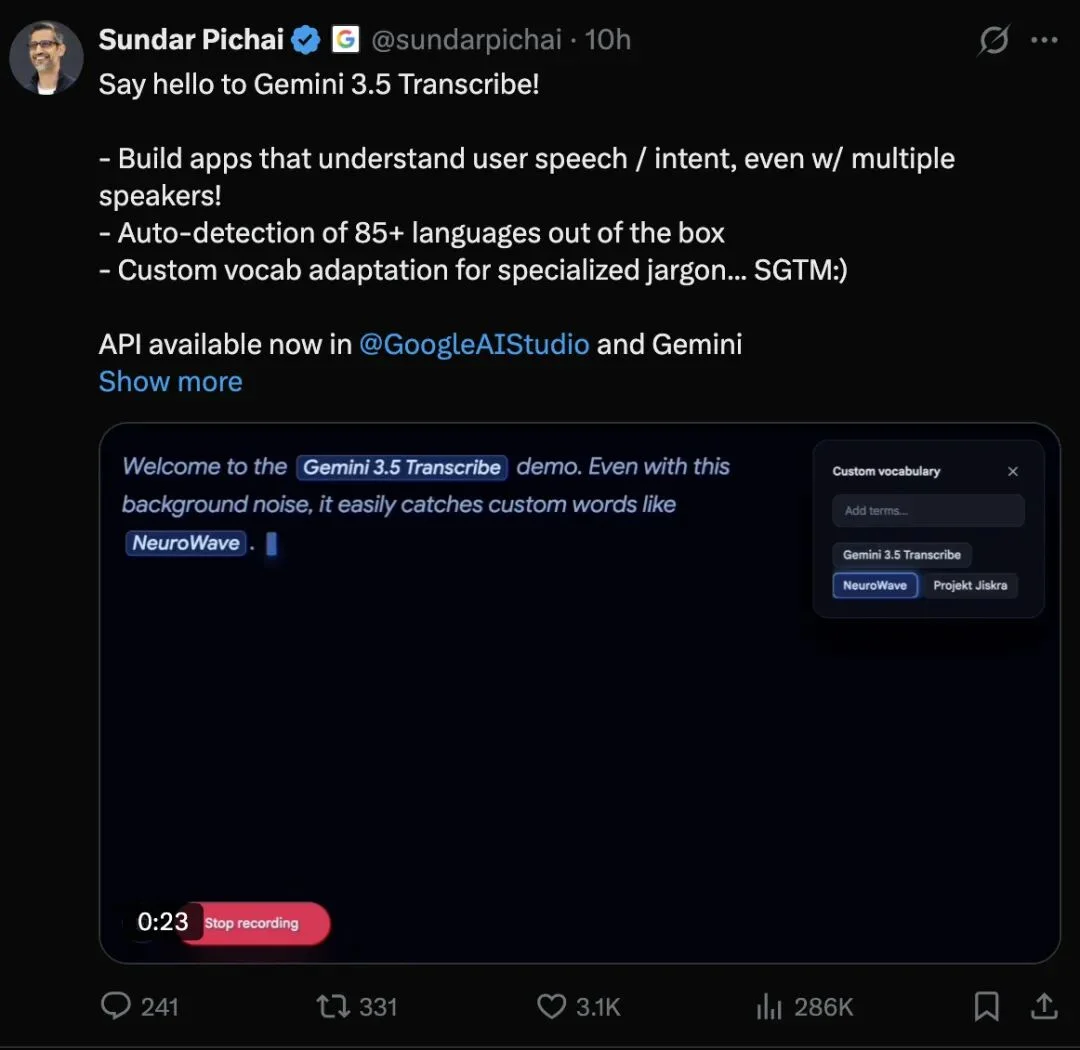
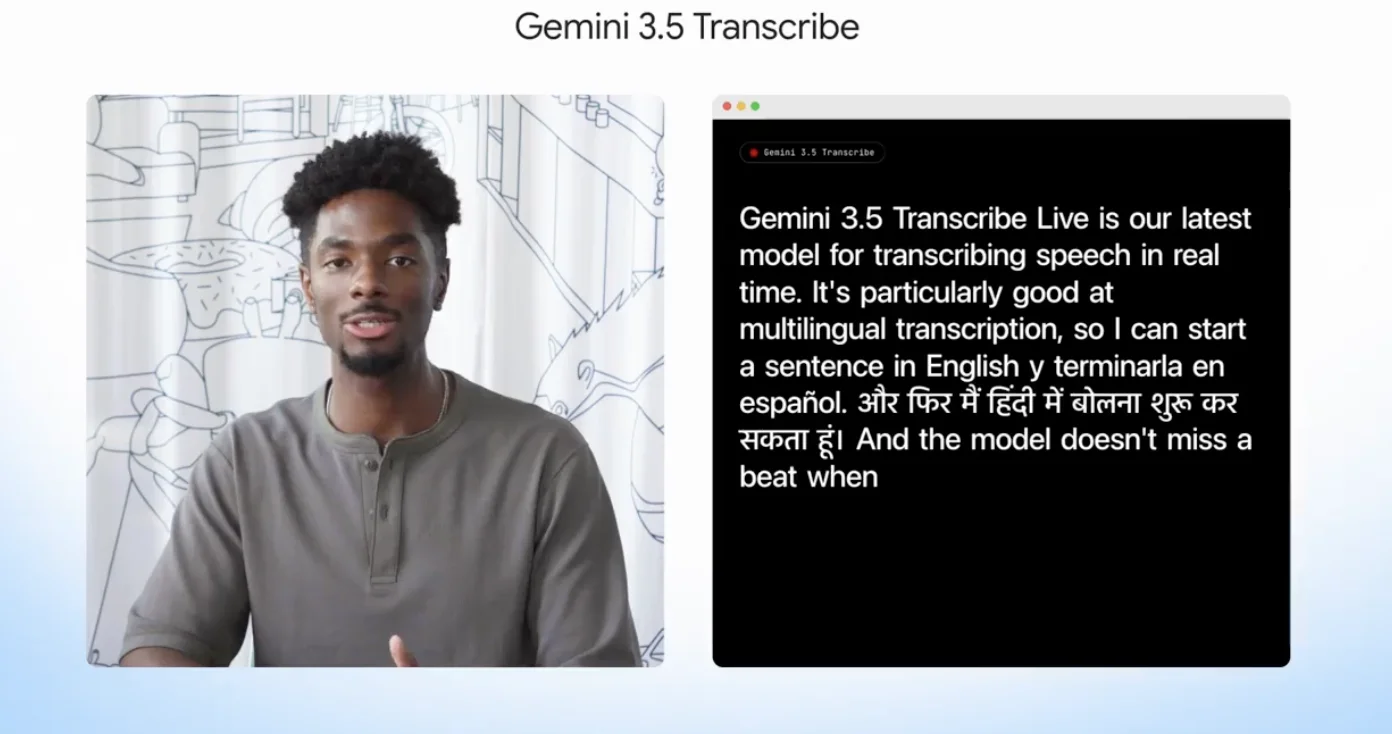
- Supports 85+ languages and regional variants, with automatic language detection—even mid-sentence or mid-conversation.
- Optimized for noisy environments, diverse accents, overlapping speakers, and domain-specific terms (e.g., technical jargon, product names).
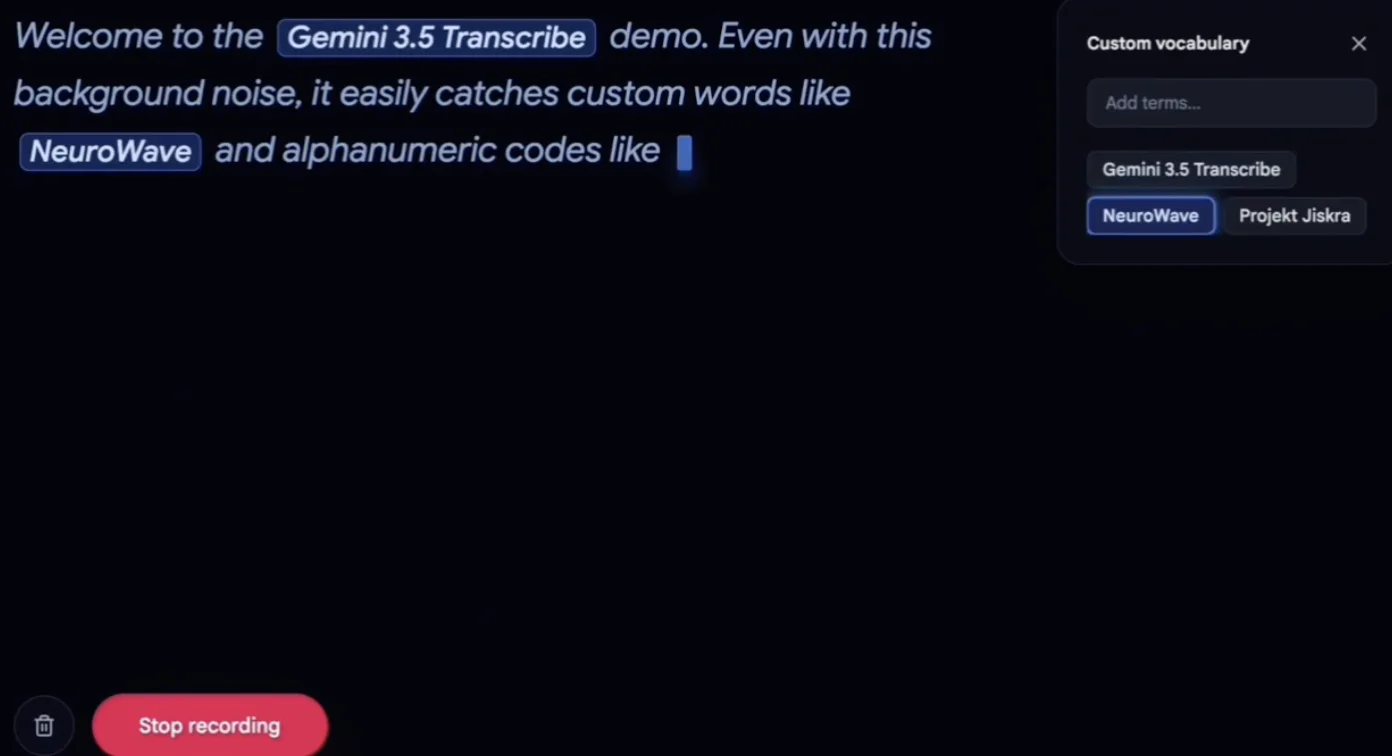
- Offers custom vocabulary injection: developers can supply up to 1,000 specialized terms (e.g., Kubernetes, BigQuery, internal acronyms); best results observed with ≤100 curated entries.
Advanced Capabilities for Structured Output
| Feature | Description | Limitations |
|---|---|---|
| Speaker Diarization | Identifies and labels up to 8 speakers, assigning utterances to individuals | Experimental beyond 3 speakers |
| Word-Level Timestamps | Precise start/end times per word — ideal for subtitling, audio search, and forensic review | Max 30-min duration when enabled |
Streaming Mode (gemini-3.5-transcribe-live) |
Sub-second latency via WebSocket; optimized for live captioning, voice input, and Voice Agents | — |
Batch Mode (gemini-3.5-transcribe) |
Higher accuracy for pre-recorded audio (meetings, interviews, calls); supports speaker separation & timestamps | Max 60-min duration |
Performance Benchmarks & Pricing
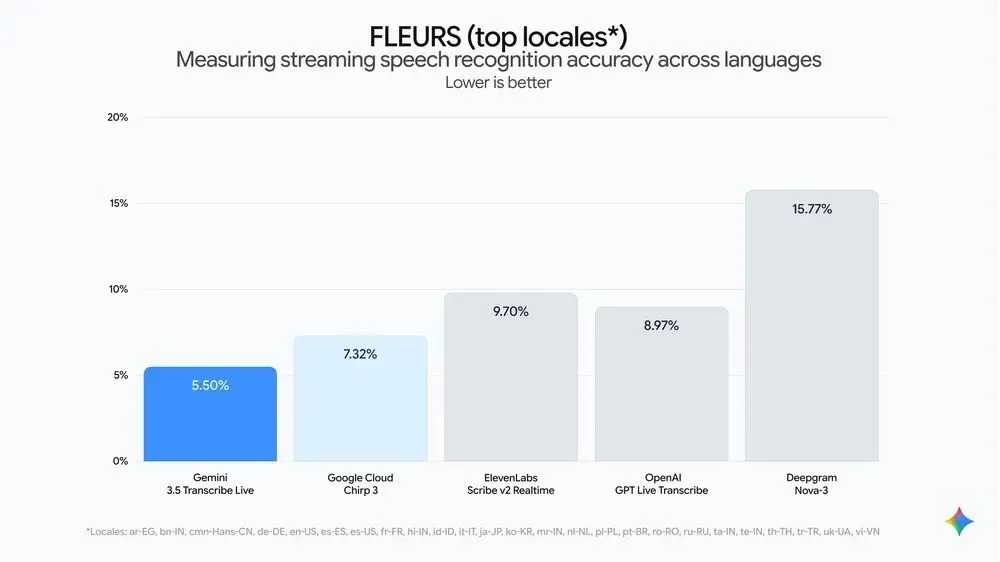
- Streaming WER: 4.0% (Artificial Analysis benchmark)
- Batch WER: 2.6%
- Latency improvement: 70% faster than predecessor Chirp 3
- Pricing:
- Streaming: $0.009/min
- Batch: $0.005/min
- Free tier available via Google AI Studio
Beyond Transcription: Enabling Voice-Native AI Workflows
Gemini 3.5 Transcribe is not a standalone tool—it’s a foundational layer for voice-first Agent ecosystems:
– Integrated into Android Gboard’s Rambler, enabling voice-to-formatted-text + voice-editing.
– Powers macOS Gemini app, allowing voice commands contextualized by on-screen documents (e.g., “summarize this PDF”, “rewrite this paragraph”).
– Serves as the input normalization engine for enterprise Agent workflows—converting messy human speech into clean, structured prompts for downstream LLMs.
Critical Considerations: Verbatim vs. Smart Modes
- Smart Transcription (default): Prioritizes readability — removes disfluencies, applies grammar rules, normalizes entities. Ideal for summaries and daily use.
- Verbatim Mode: Preserves every hesitation, repetition, and false start — essential for legal, journalistic, or medical documentation.
⚠️ Trade-off warning: “Cleaner” ≠ “more accurate” in high-stakes contexts. Developers must select mode deliberately — not by default.
Strategic Perspective: Not a Step Back — But a Necessary Layer
While competitors spotlight end-to-end voice agents, Google’s focus on robust, production-grade speech understanding addresses a critical bottleneck: unreliable input degrades all downstream intelligence. Background noise, code-switching, speaker overlap, and domain ambiguity remain persistent challenges — and Gemini 3.5 Transcribe directly mitigates them.
Its strategic value emerges only when embedded across the stack: Gboard, Chrome, Gemini, Workspace, and Enterprise Agent Platform. As one analyst noted: “This isn’t about winning a benchmark — it’s about ensuring the first link in the voice-to-action chain never fails.”
References
• Official Announcement
• API Pricing & Docs